Parallelization with Python
Data Science Special Topics · NC State University Libraries
While we get started
Open the materials
go.ncsu.edu/parallel-python
Slides first, then the notebook. Want your own laptop's cores? Do Setup, part B, while we talk. Colab needs nothing.
Data Science Services
Our services: consulting, workshops and instruction, specialized spaces. What we do: finding data, wrangling data, analyzing data, visualization, geographic information systems (GIS), software access.
Who we are
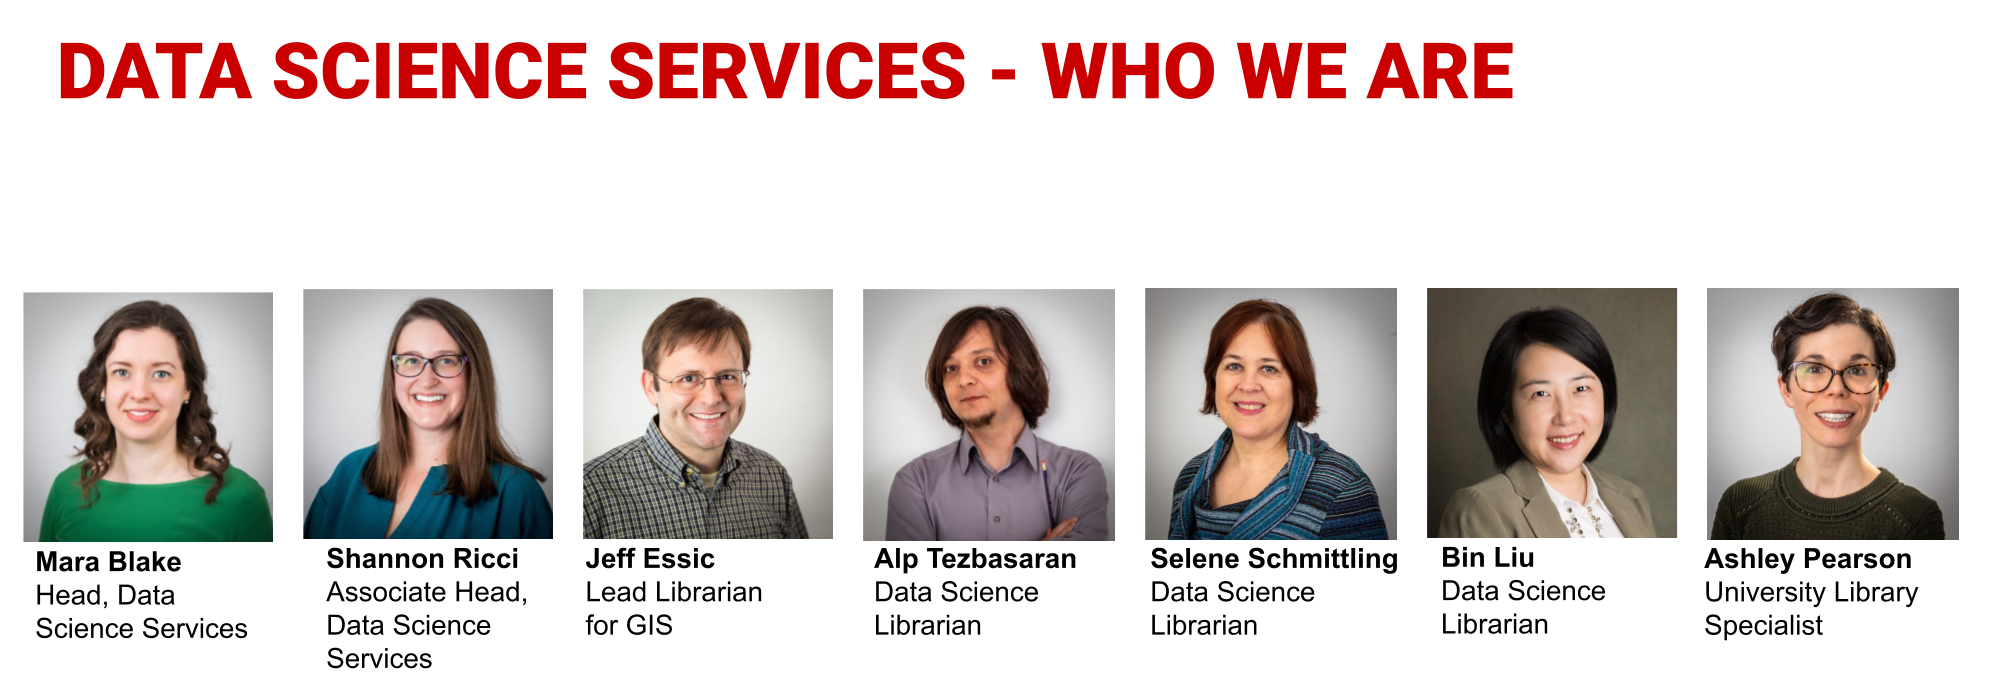
Our team comes from a variety of academic backgrounds, including nuclear engineering, electrical engineering, industrial and environmental engineering, marine ecology, information science, natural resources, business administration, and geographic information sciences.
How to contact us
How to contact us: go.ncsu.edu/getdatahelp. Email us, book a 30-minute appointment with a Data Science Consultant, or reserve a workstation in the DXL or Dataspace. All communication with the program is through getdatahelp@ncsu.edu.
Today's finish line
- Learn the types of parallelization and where your own work fits
-
Spread an "embarrassingly parallel" task across cores with Python's
multiprocessing - Time it across core counts to see where the gains level off
- See a case where parallel is slower, and why
Welcome and the main idea
This laptop: 14 cores
Text alternative: A processor with 14 cores: 10 large performance cores (P) and 4 smaller efficiency cores (E). All 14 are idle. A code card tagged a fire simulation shows a loop, for forest in forests: burn(forest), that starts running. Exactly one core lights up. The meter reads 1 of 14 cores busy, 7%. The other 13 cores are idle, shown with dashed outlines, and a callout says 13 cores waiting. All 14 cores light up. The meter reads 14 of 14 busy, 100%. The caption says: This workshop: how to use the rest. The code card leaves, the chip moves left, and a card titled Yours? appears with the code import os and os.cpu_count() and three rows: this laptop 14, Google Colab 2, and yours with a question mark.
Our example: a forest-fire simulation
Text alternative: The question: how dense can a forest be before a fire can cross it? You can't test that by burning real forests, so we simulate it. A forest 64 cells across with 60 percent trees sits beside three rules: trees are scattered at random, 60 percent of the cells; fire starts in every tree on the left edge; each step it spreads to the four neighboring trees. The fire spreads through the forest while the burned counter climbs to 56 percent, and a code card reads burn(0.60, seed=28, size=64) returning 0.56: one run is one function call, and it returns one number, the fraction of trees burned. 48 dots on a zero to 100 percent axis of trees burned show 48 random forests at 60 percent trees, with 48 different answers, so to trust the answer you run it many times, at every density. 21 densities times 48 forests is 1,008 runs, and none needs another's result. Fire scientists run far richer models, thousands of times; ours keeps one idea, fire jumps from tree to tree. Your own simulations have the same shape: one model, many settings.
The landscape
Reading the lanes
Text alternative: Twelve identical red task blocks wait in a queue at the left. To their right is one empty lane, worker 1, with a time axis. The legend along the bottom reads: lane equals worker, block equals task, gray equals overhead, line equals finish. The twelve tasks slide into worker 1's lane one after another. The finish line drops at 12 units: 1 worker, 12 units. Three more lanes appear and the tasks are dealt out round-robin to four workers. A new finish line lands at 3 units: 4 workers, 3 units, 4 times faster. The old 12-unit line stays as a faint ghost. A gray overhead sliver now comes before every task, and the finish line slides right to about 3.6 units: 3.4 times faster, not 4. Handing out work isn't free.
Question 1: What do you split?
Text alternative: Four gray labels sit in a row under the title: the inputs, the data, the space and the steps. The inputs: three whole forests with 45, 60 and 75 percent trees go to workers W1, W2 and W3, one forest each, so each worker gets whole simulation runs, like the 1,008-run sweep. The data: the 60 percent forest is cut into four bands of 16 rows for workers W1 to W4, each band shows its tree count (610, 595, 623, 617), and the four counts slide together into one total of 2,445 trees. The space: the same banded forest burns, and small two-way ticks flash on the band edges where the fire crosses, because each worker owns a region and neighbors trade their edges every step, which is domain decomposition. The steps: three stage boxes, make a forest, burn it and summarize, belong to workers W1, W2 and W3, and small forest tiles pass through them one after another until each ends as a number (0.08, 0.56, 0.99), which is a pipeline. All four ways to split the problem sit small in a 2 by 2 grid, with the inputs outlined in red and tagged today's demo.
Question 2: How often do the pieces talk?
Text alternative: Four empty panels sit side by side, headed Never for the inputs, Once at the end for the data, Every step for the space and At each handoff for the steps, each with three empty lanes. In the Never panel each of the three lanes fills with its own blocks, with no arrows between lanes, and all three finish together, and a red tag says today. In the Once, at the end panel each lane fills with its own blocks, and then arrows from every lane converge on one small combine block labeled sum. In the Every step panel the lanes work in rounds, each with a short block, gray waiting up to a dashed barrier and arrows between neighboring lanes, before the next round starts. In the At each handoff panel the lanes become pipeline stages and items 1 to 4 move through on a diagonal, with an arrow each time an item passes to the next stage. The four panels dim and two small pictures appear side by side, threads in one shared memory where talking is cheap but they can collide, and processes in separate memories that talk by sending parcels, so every multiprocessing message is a parcel and the more they talk the more they wait.
Waiting vs. computing
Text alternative: Two rows each run on one worker, one task after another: downloading 4 files, where each short red block is followed by a long hatched gray wait for the network or the disk, and burning 4 forests, where each task is solid red. In the downloading row one worker juggles all four files, so their waits overlap on the same lane, staggered, and the finish line jumps left; the label says threads and asyncio can do this, but not today. In the burning row four threads get four lanes, but a single round token labeled GIL hops between them, only the lane holding it is red at any moment, and the finish line does not move; the label says threads take turns running Python code, one at a time. The burning row switches to four processes: each lane gets its own token, all four compute at once, and the finish line moves to a quarter of its old distance; the label says separate processes each run their own Python, which is multiprocessing. A muted footnote says Python 3.13 and later offer an optional build without the GIL, but standard installs and Colab still have it.
For waiting: threading and asyncio
Threads: threading Several threads share one process and its memory. Python's lock, the GIL, lets one thread run Python code at a time, so threads overlap waits, not work. The easy way in: a thread pool from concurrent.futures.
with ThreadPoolExecutor(8) as ex:
    pages = list(ex.map(fetch, urls))
One thread, many waits: asyncio An event loop runs functions that pause at await while they wait, and runs another one meanwhile. Thousands of waits at once, with async libraries such as httpx.
async def main():
    jobs = [fetch(u) for u in urls]
    return await asyncio.gather(*jobs)
pages = asyncio.run(main())
Not today: a forest fire computes; it doesn't wait. Reach for these when your program mostly waits on the network or the disk: downloads, web APIs, databases.
For computing: multiprocessing
Separate processes, each with its own memory and its own Python, compute at the same time. The cost: starting them, and sending inputs and results between them.
| In code | Use it for |
|---|---|
pool.map(run, tasks) today |
One function, many inputs, results in order |
pool.imap_unordered(run, tasks) |
Results as they finish: progress bars, long lists |
pool.starmap(burn, pairs) |
A function with several arguments |
pool.apply_async(burn, (0.6, 1)) |
Different jobs, sent one at a time |
Process(target=job).start() |
One long job beside your program |
ProcessPoolExecutor().submit(run, task) |
The same pool, concurrent.futures style |
When processes must talk: Queue, Pipe, shared_memory and Manager.
Where parallelism lives
Text alternative: A breadcrumb along the top reads core, chip, computer, cluster, with core marked, and one big red square stands for a single core, labeled: One core, a plain loop. The core opens to show a vector unit, a row of 8 slots that handle 8 numbers in one step, beside a plain loop that handles one number at a time, with the label: One core, vectorized, vectorize first. The core shrinks into a chip with 14 cores, drawn as in the first animation, and all 14 light up under a red today tag, with the label: One chip, multiprocessing, concurrent.futures, joblib. The chip shrinks into a computer, where the CPU chip sits next to a GPU drawn as a dense grid of tiny cores, with the label: One computer, a GPU splits the data across thousands of small cores, PyTorch, CuPy, Numba. The computer shrinks into one node of a cluster of rack nodes, with the label: Many computers, a cluster such as NC State's Hazel, job arrays, Dask, Ray, mpi4py. The view zooms back in to the chip, the breadcrumb marks chip with You are here under it, and the label again reads: One chip, multiprocessing, concurrent.futures, joblib.
Why not a GPU for everything?
Text alternative: On the left is a CPU chip with 14 cores and on the right is a GPU drawn as a dense grid of tiny cores grouped in blocks of 32, with captions saying this laptop has 14 CPU cores and an NVIDIA T4, the GPU Colab's free tier usually gives you, has 2,560 cores. Each CPU core now shows a different small job, a forest, a file, a chart or a loop, while one group of 32 GPU cores lights up together and does the same step at the same moment, each core on different data. The group of 32 meets an if tree, else branch, so half the group runs while the other half waits in gray and then the halves swap, because cores in one group that need different branches take turns. A gray parcel is copied along a bus from computer memory into the GPU's own memory, as on most GPUs, with a note that Apple's chips share memory between the CPU and the GPU. Two cards give the verdict: a GPU wins on the same simple math on huge arrays, such as images, matrices and neural networks with CuPy, PyTorch or JAX, and a CPU wins on different, branchy work and ordinary Python, and a last line says our forest fire follows the flames with a queue, so a GPU could burn thousands of forests at once only after a rewrite as array updates, which is the price.
Your decision: two questions
Text alternative: Three column heads read: What do you split, How often do the pieces talk, and Reach for. Row one, in red: split the inputs, the pieces never talk, and you reach for multiprocessing.Pool, which is today's choice. Row two: split the data, the pieces talk once at the end, and you reach for Pool.map and then combine, or Dask DataFrame when the data is bigger than memory. Row three: split the space, the pieces talk every step, and you reach for MPI with mpi4py, or Dask's map_overlap. Row four: split the steps, the pieces talk at each handoff, and you reach for queues, Dask or workflow tools. Three side checks appear under the table: mostly waiting for the network or disk means threads or asyncio, already NumPy-shaped means vectorize first and a GPU if it's huge, and bigger than one machine means a cluster. The full table stays on screen with row one in red, and the caption asks: Where did your task land?
How multiprocessing works
Inside multiprocessing
Text alternative: A big box labeled your notebook holds a small memory panel with tasks = [...] and run, labeled from fire.py. Pool(4) starts four worker boxes on the right, each labeled a fresh Python with its own empty memory, and the caption says each worker is a separate Python process with its own memory. A small file icon, import fire, travels along the pipes and slides into each worker's memory, because workers start fresh and import your function from a file, which is why it lives in fire.py and not in a notebook cell. The task (0.60, 28) goes into a parcel labeled pickled, travels along a pipe to worker 1 and is unpacked, worker 1 turns red, the result 0.56 travels back in its own parcel, and then parcels flow to all four workers at once. A callout says every parcel costs time: a lot of work per parcel is worth it, but with tiny work the shipping costs more than the work.
pool.map, step by step
Text alternative: On the left, code up to the loop line results = [run(t) for t in tasks] is highlighted; on the right, one lane holds the 12 numbered tasks in a row, labeled the loop you know. The line with Pool(4) as pool appears and is highlighted, and three more lanes appear, labeled four workers start. The line results = pool.map(run, tasks) is highlighted and each worker takes the next task as soon as it is free, so the lanes fill unevenly but stay busy and a new finish line lands far to the left of the loop's, labeled map hands each free worker the next task. A results row under the lanes fills in list order, 1 to 12, as the blocks finish out of order in time, labeled results come back in the same order as the loop. The loop line and the two Pool lines sit side by side, each with the same row of results 1 to 12, under the caption: Two lines changed. Same answers.
Demo 1: spread it across cores
One task, then a thousand
Text alternative: Three forests 64 cells across, with 45, 60 and 75 percent trees, stand unburned above a code card with three calls of burn with the same seed and the three densities. The three fires burn together and the calls return 0.08, 0.56 and 0.99, so different inputs give different answers and seeing the pattern means running it many times; one run takes about 40 milliseconds at the workshop's real 450 by 450 size. The sweep is 21 densities times 48 seeds, 1,008 calls drawn as tiles with one column per density, and because no call needs another's result it is embarrassingly parallel and takes about 37 seconds one after another. The tiles become dots on a plot of the fraction of trees burned against tree density, with a red mean line that rises steeply at the tipping point near 59% trees, and a banner says the same 1,008 runs come next on 14 cores.
1 worker vs. 14 workers
Text alternative: Two panels share a time axis from 0 to 40 seconds, a top panel with one lane for 1 worker and a bottom panel with 14 thin lanes for 14 workers, and both clocks read 0.0 seconds. Both panels replay the same 1,008 forest runs from real timings: the 14 workers finish at 3.6 s, where a finish line drops, while the single worker keeps going until 38.2 s. The bottom panel zooms to 0 to 4 seconds so the real blocks show: each block is one forest, short for sparse forests and long for dense ones, and a worker takes the next task as soon as it is free. A dotted line marks where a perfect 14 times faster would have finished, at 2.7 s, short of the real 3.6 s, and the label says about 10 times faster on 14 cores, not 14, with the reason coming next.
Demo 2: where the gains level off
Where the gains level off
Text alternative: A chart of how many times faster the 1,008-forest sweep runs against the number of workers, 1 to 16, with a dashed diagonal marking perfect scaling. Measured on this laptop, the points for 1, 2, 4, 6, 8 and 10 workers rise close to the perfect diagonal. The points for 12, 14 and 16 workers bend flat at about 10 times faster, with bands for the 10 performance cores, the 4 efficiency cores that add a little, and no cores left. Amdahl's law, as an example and not a measurement: if 10% of the work can't be split, the total time never drops below that part, so the faint curve tops out at 10 times. Your machine sets the ceiling; overhead and serial parts lower it.
Your ceiling
Text alternative: The measured speedup curve of this 14-core laptop: times faster against workers, flattening near 10 times faster. A cap line at 2 times faster marks Google Colab: 2 cores, at most 2 times faster. A band from 8 to 12 times faster marks a typical laptop: 8 to 12 cores, at most 8 to 12 times faster. A dashed line rising off the top of the chart marks a cluster node: dozens of cores, at most dozens of times faster. The notebook draws your own curve; share your number in the chat.
Demo 3: slower than not
When parallel is slower
Text alternative: A tiny 4 by 4 forest stands next to a big 450 by 450 one: the big run takes about 40 milliseconds, the tiny one about 10 microseconds, with the same code. 3,000 tiny runs replay on 14 lanes with one task per parcel as thin red slivers between long gray gaps of waiting for the next parcel, and a scoreboard shows the plain loop at 0.98 seconds against the pool at 1.62 seconds, 1.65 times slower, like hiring movers to carry one spoon at a time. With chunks of 54 tasks per parcel the lanes fill with solid red blocks and finish at 11.6 ms instead of 49.5 ms; the scoreboard adds the pool with 1,786 tasks per parcel at 0.15 seconds, 6.5 times faster: chunksize bundles tasks into bigger parcels. A rule-of-thumb card: give each parcel real work, milliseconds not microseconds; Pool.map bundles by default; imap and concurrent.futures send one task per parcel unless you set chunksize.
Your own work
Where to go next
Text alternative: Step 1 of a four-step ladder: concurrent.futures, the same idea with a newer interface, shown with ProcessPoolExecutor and ex.map. Step 2: joblib, what scikit-learn's n_jobs uses, shown with Parallel and delayed. Step 3: Dask and Ray, for bigger data and many machines. Step 4: a cluster, with job arrays on NC State's Hazel, and mpi4py when the pieces must talk. A footer card: for help with your own project, go to go.ncsu.edu/getdatahelp.
Your turn
Open the notebook
Colab: nothing to install
- go.ncsu.edu/parallel-python → Notebooks → Learner notebook in Colab
- Click Copy to Drive
- Run the two Setup cells: Shift-EnterShift-Enter
JupyterLab: all your cores
- go.ncsu.edu/parallel-python → Setup, part B, best done during the slides
uv run jupyter lab, and open the notebook- Run the two Setup cells: Shift-EnterShift-Enter
The first Setup cell downloads fire.py and lanes.py next to the notebook. The filled notebook has every answer.
If there's time: split the data
Split the data
from multiprocessing import Pool
from fire import count_band

size = 8000                                     # one forest, 64 million cells
bands = [(size, 0.6, 1, first, 500) for first in range(0, size, 500)]

with Pool() as pool:
    counts = pool.map(count_band, bands)        # each worker builds and counts its own bands
total = sum(counts)                             # combine once, at the end
Send where the slice is, not the slice, like each worker reading its own chunk of a big file.
In the notebook: the bonus section.
Ways to split the work
Task parallelism The inputs: sweeps, ensembles, many files.
Pool, joblib, job arrays
Data parallelism The data: map-reduce, split-apply-combine.
Pool.map plus combine, Dask DataFrame, Polars, Spark
Domain decomposition The space: grids and meshes, with halo exchange (neighbors swap borders).
mpi4py, Dask's map_overlap, PETSc via petsc4py
Pipelines The steps: stages and queues.
multiprocessing.Queue, Dask, Snakemake, Nextflow
Where the parallelism runs
Vectorizing One core: compiled loops over whole arrays.
NumPy, Numba
Shared-memory threads One process: threads share memory.
Numba prange, NumPy's multithreaded math libraries, the optional free-threaded Python 3.13+
Separate processes One machine: each process has its own memory.
multiprocessing, concurrent.futures, joblib
GPUs One GPU: the data across thousands of cores.
CuPy, PyTorch, JAX
Clusters and message passing Many machines.
mpi4py, Dask, Ray, job arrays
Concurrency for waiting Not parallel computing, but often confused with it.
threading, asyncio
Questions
Tell us how we did
Data Science Services · go.ncsu.edu/parallel-python